Backup & restore operator for Kubernetes · Postgres 15–17 · PostGIS · MySQL 8.4
Every second of your database, restorable.
Keeper backs up the databases you run in Kubernetes to any S3 bucket and streams every change as it happens. Pick a moment from the last few weeks and you get that exact database back in a throwaway sandbox, with checks already run, in less time than it takes to open a ticket.
- Restore to
- 2026-10-07 09:41:27 UTC
- Base backup
- 20261007T020712Z-4c1e
- Then replay
- 114
$ keeper restore team/app --at 2026-10-07T09:41:27Z --wait
Drag across the window. Amber ticks are the nightly full backups; the blue band is the change stream between them. An illustration of a prod policy: nightly fulls, 7-day window.
- 9sto restore a 644 MiB Postgres database into a sandbox: fetch, decrypt, recover and run checks
- 4.2×smaller in the bucket: a 683 MiB physical backup stored as 161 MiB
- 72MiB/slogical full backup throughput on 4 vCPU, streamed with no temp files
- 20msp99 for the console overview with 1,000 databases and 100,000 backups
Measured with make test-perf and make test-ui on the k3d test harness (4 vCPU, in-cluster MinIO). The numbers are in the repository's docs/PERF.md.
One minute, start to restore.
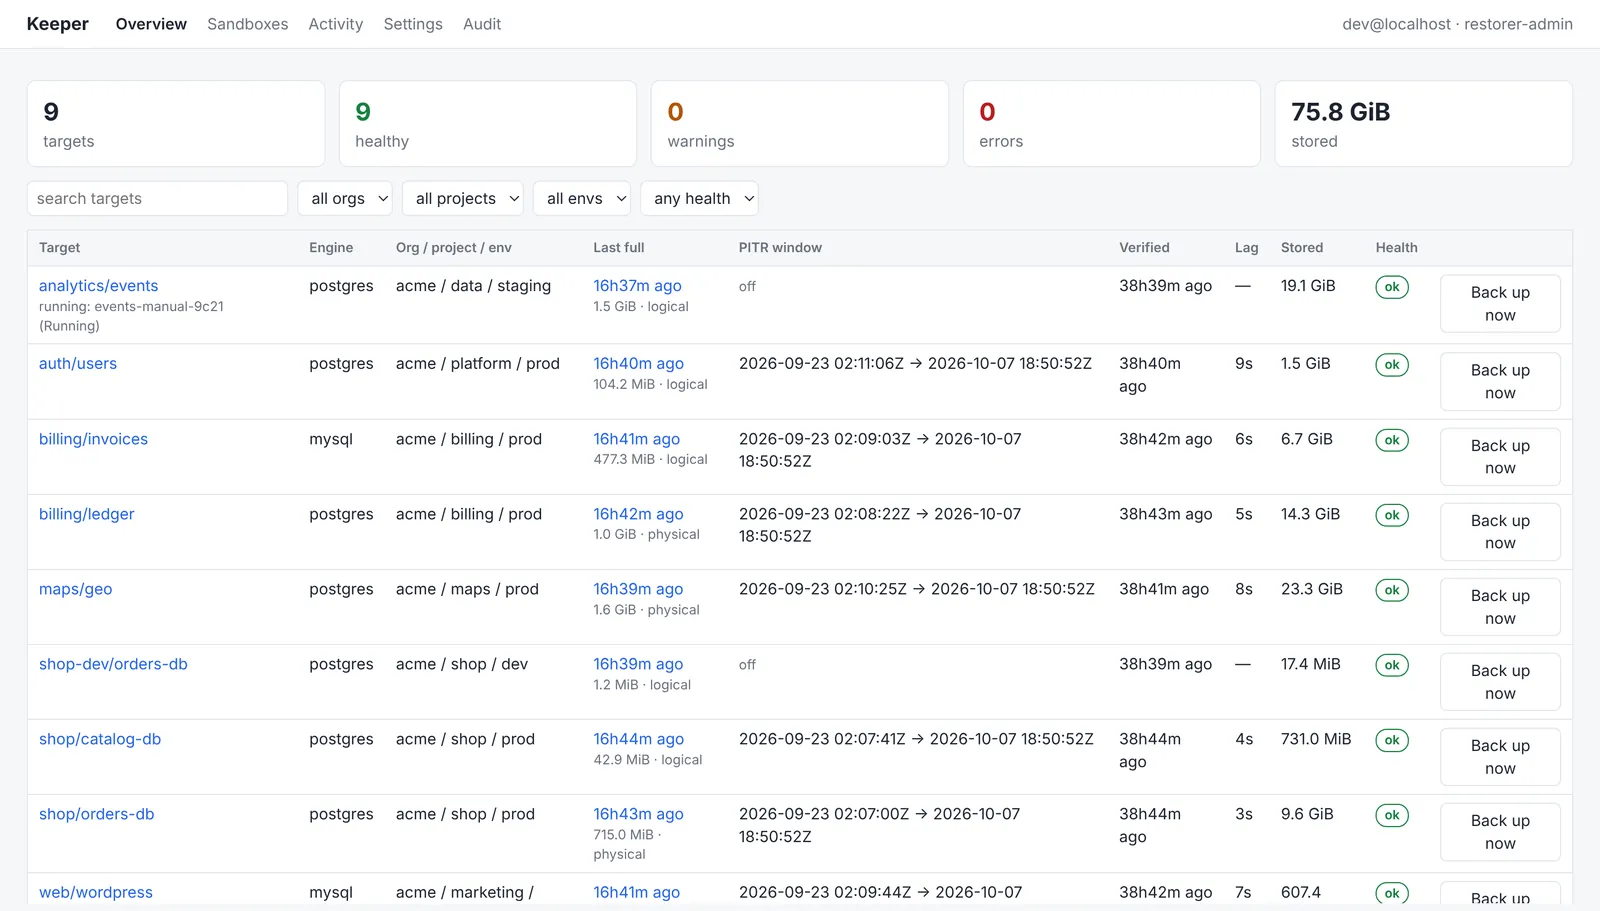
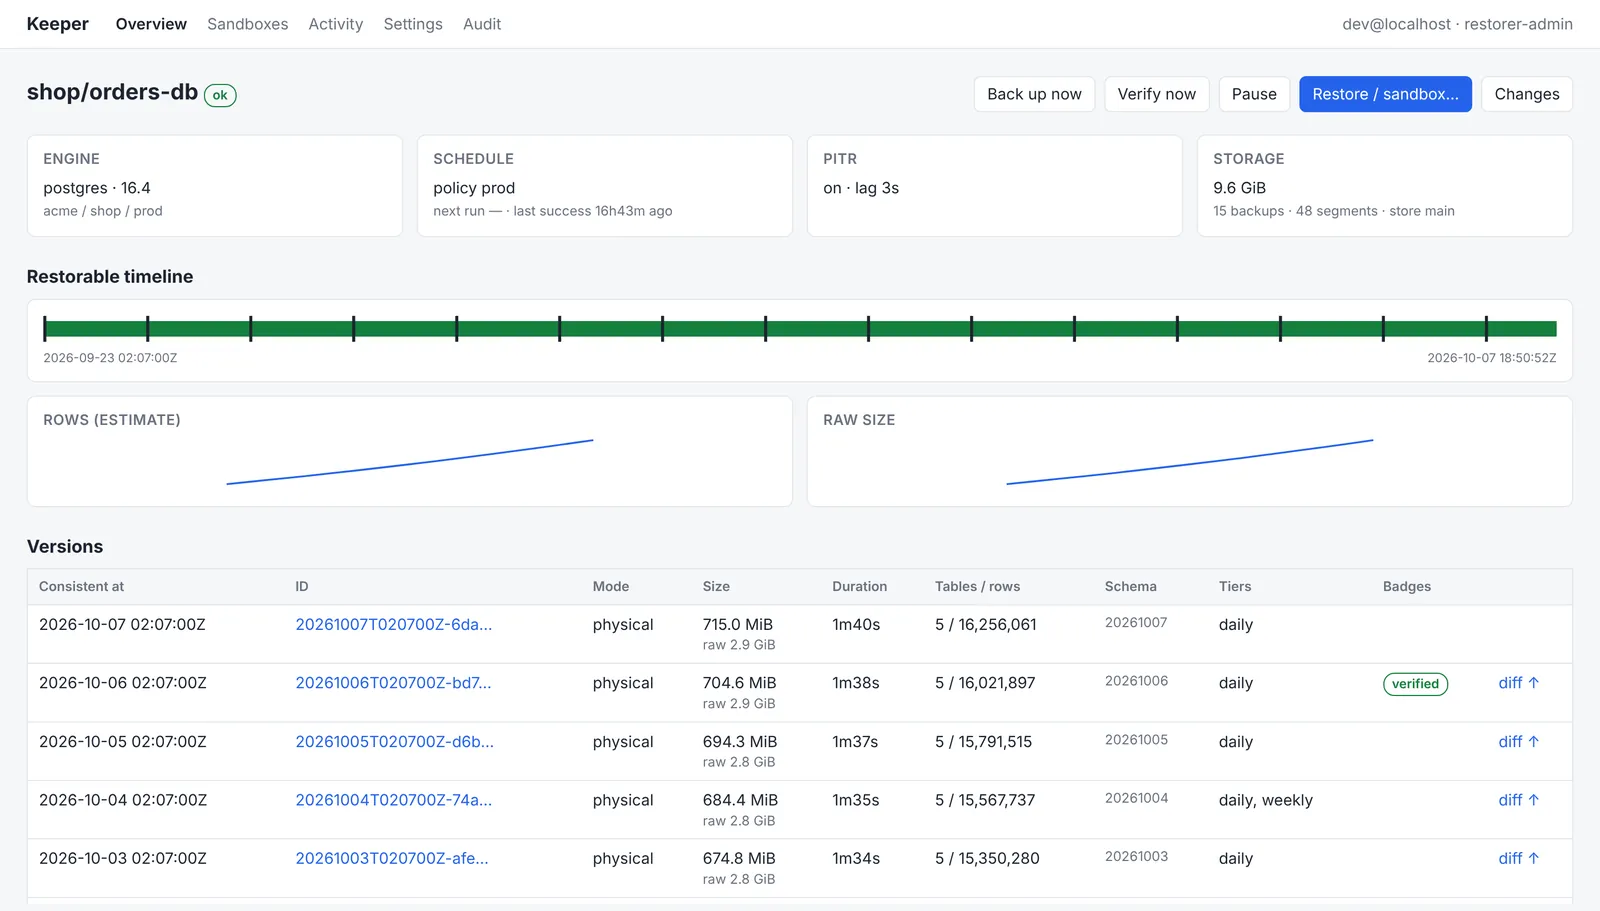
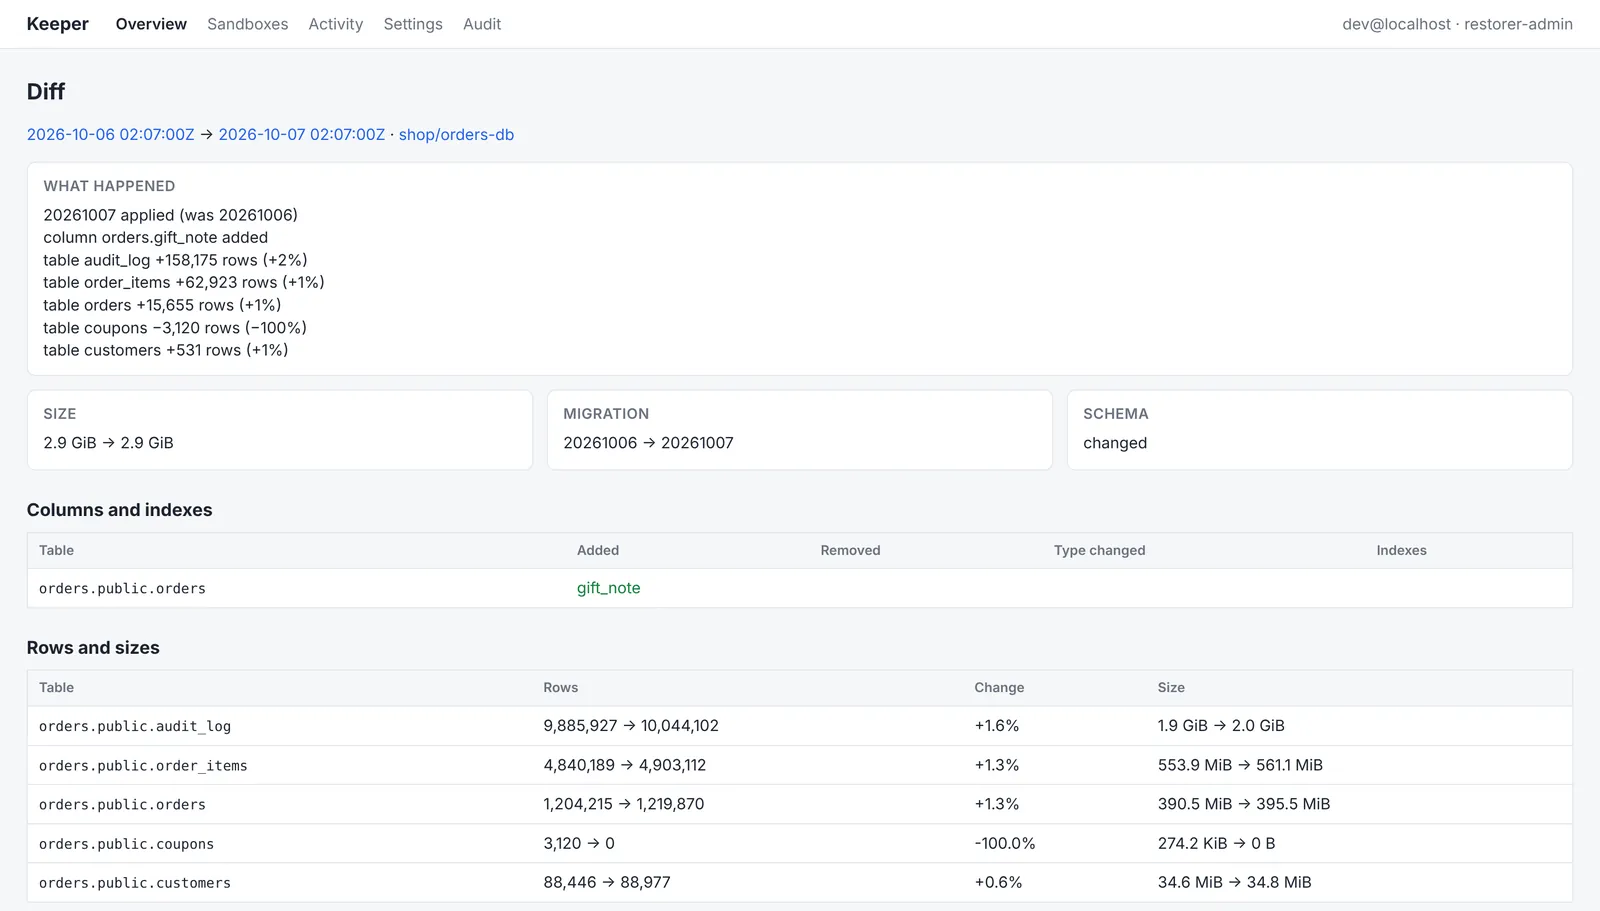
Real commands and the real console against a demo catalog: list every database, see what changed overnight, restore it into a sandbox.

The console
The CLI
$ keeper targets
TARGET              ENGINE    ORG/PROJECT/ENV      LAST FULL             PITR WINDOW                                  STORED    HEALTH
analytics/events    postgres  acme/data/staging    2026-10-07 02:11:47Z  -                                            19.1GiB   ok
auth/users          postgres  acme/platform/prod   2026-10-07 02:11:06Z  2026-09-23 02:11:06Z → 2026-10-07 18:50:52Z  1.5GiB    ok
billing/invoices    mysql     acme/billing/prod    2026-10-07 02:09:03Z  2026-09-23 02:09:03Z → 2026-10-07 18:50:52Z  6.7GiB    ok
billing/ledger      postgres  acme/billing/prod    2026-10-07 02:08:22Z  2026-09-23 02:08:22Z → 2026-10-07 18:50:52Z  14.3GiB   ok
maps/geo            postgres  acme/maps/prod       2026-10-07 02:10:25Z  2026-09-23 02:10:25Z → 2026-10-07 18:50:52Z  23.3GiB   ok
shop-dev/orders-db  postgres  acme/shop/dev        2026-10-07 02:12:28Z  -                                            17.4MiB   ok
shop/catalog-db     postgres  acme/shop/prod       2026-10-07 02:07:41Z  2026-09-23 02:07:41Z → 2026-10-07 18:50:52Z  731.0MiB  ok
shop/orders-db      postgres  acme/shop/prod       2026-10-07 02:07:00Z  2026-09-23 02:07:00Z → 2026-10-07 18:50:52Z  9.6GiB    ok
web/wordpress       mysql     acme/marketing/prod  2026-10-07 02:09:44Z  2026-09-23 02:09:44Z → 2026-10-07 18:50:52Z  607.4MiB  ok
$ keeper diff 20261006T020700Z-bd79 20261007T020700Z-6da5
from  20261006T020700Z-bd79 (2026-10-06 02:07:00Z)
to    20261007T020700Z-6da5 (2026-10-07 02:07:00Z)

20261007 applied (was 20261006)
column orders.gift_note added
table audit_log +158,175 rows (+2%)
table order_items +62,923 rows (+1%)
table orders +15,655 rows (+1%)
table coupons −3,120 rows (−100%)
table customers +531 rows (+1%)

14 segments in between:
  00000001000000A100000000  18:51:32–19:20:32 · 800 commits · audit_log +3348 / ~1116 / −83 · order_items +1327 / ~442 / −33 · orders +330 / ~110 / −8 · customers +11 / ~3 / −0
  00000001000000A100000001  19:21:32–19:50:32 · 813 commits · audit_log +3352 / ~1116 / −83 · order_items +1328 / ~442 / −33 · orders +330 / ~110 / −8 · customers +13 / ~3 / −0
  00000001000000A100000002  19:51:32–20:20:32 · 826 commits · audit_log +3356 / ~1116 / −83 · order_items +1329 / ~442 / −33 · orders +330 / ~110 / −8 · customers +15 / ~3 / −0
$ keeper restore shop/orders-db --at 20261006T020700Z-bd79 --ttl 6h --reason "coupons truncated"
restore orders-db-sandbox-60414a15fc created (sandbox from 20261006T020700Z-bd79, 0 segments)
restore  shop/orders-db-sandbox-60414a15fc

$ keeper sandbox list
NAME      ENGINE    SOURCE            OWNER               PHASE         EXPIRES               IN-CLUSTER
sbx-7f3a  postgres  shop/orders-db    maria@acme.example  Ready         2026-10-08 00:37:32Z  keeper-sbx-sbx-7f3a.keeper-sandboxes.svc:5432
sbx-c210  mysql     billing/invoices  dev@acme.example    Provisioning  -
Output from the demo server in the repository: go run ./hack/demo, then point the CLI or a browser at it.
Restore anywhere, without touching production.
A restore is a Kubernetes resource like any other. Ask for a time or a backup ID and pick where it goes. Keeper plans the base backup and the changes to replay, then runs your checks before it calls the restore a success.
A throwaway copy
A private database with a TTL, credentials and a read-only query console. It cleans itself up.
--to sandbox --ttl 6hA new database
Restored and checked in a staging sandbox, then copied to a new name. Existing objects are never overwritten.
--to new --database app_copyRoll back for real
Takes a safety backup first and asks you to type the target's name. Needs the restorer-admin role.
--to in-place --confirm appA dump file
A decrypted, compressed logical dump behind a link that expires in an hour. Audited.
--to downloadSmall enough to forget it is there.
Keeper is one Go binary. The controller and the API only schedule and read; bytes move in short-lived Jobs that exit when they are done, so nothing heavy sits in your cluster between backups.
Working set reported by the kubelet in the k3d test cluster (12 databases) after the end-to-end and chaos suites; CPU at rest is a few millicores. Each database with point-in-time recovery also runs a streamer, about 70 MiB while it streams.
Fast by construction
Streaming pipelines with no temp files, parallel multipart uploads, multi-threaded zstd, and an in-memory catalog behind a console that answers in milliseconds.
Reliable by construction
Crash-only design: any pod can die at any moment. State lives in CRDs and S3, a backup exists only once its manifest is written last, and nothing waits forever.
Know what changed between two versions.
Every backup carries an inventory of its tables, rows and sizes. Every change segment carries a summary of what it did. So before restoring anything, you can see which version still had the rows you lost.
- Diffs between any two backups. Schema changes, row counts and size per table.
- Change summaries per WAL or binlog segment. Inserts, updates, deletes and DDL per table, so a TRUNCATE at 22:48 is easy to find.
- Masked previews. Sample rows with the columns you list masked, readable with a catalog key that cannot decrypt the data itself.
Built for the night something goes wrong.
Change streaming
Keeper's own WAL receiver on a replication slot for Postgres and mysqlbinlog for MySQL. The window reaches the present, even on a quiet database.
Verified, not hoped for
Scheduled verification restores run your SQL checks against a real restore and mark the backup verified. Their restore time is exported as a metric.
Encrypted before it leaves
Every object is encrypted client-side with age to your keys. The bucket never sees plaintext, and the console's catalog key cannot read data.
Compressed by default
zstd at a level you choose per policy, applied once in the pipeline. Dump tools run uncompressed, and the database server never spends CPU on it.
Never hangs
No mounts or block devices; databases only over the network. Every stream has a progress watchdog, and every tool runs in its own process group.
Crash-only
Kill any pod at any moment. A backup exists only once its manifest is written last, and the chaos suite kills Keeper mid-backup to prove it.
Gentle on production
Least-privilege, read-only users. Per-host slots, bandwidth limits, and a load guard that postpones a backup when the server is busy.
Console, CLI and API
One JSON API described by OpenAPI, with roles from Cloudflare Access. Every write and every query is audited.
GitOps native
Stores, policies, targets and restores are CRDs. Retention tiers, alerts and a Grafana dashboard ship with the chart.
Data moves in Jobs, never in the controller.
The controller only schedules. Movers and streamers carry the bytes through one streaming pipeline straight into your bucket, and the restorer brings them back.
More than a nightly dump in a bucket.
| When you need to… | cron + pg_dump script | Keeper |
|---|---|---|
| Get back to 09:41:27 | Last night's dump, up to 24 h lost | Any second in the window |
| Prove a backup restores | Find out during the incident | Scheduled verification restores with your checks |
| Find the version with the missing rows | Restore several and look | Diffs and change summaries in the console |
| Look without risk | Restore over a shared staging database | A private sandbox with a TTL |
| Keep the bucket blind | Server-side encryption, if configured | Client-side age encryption to your keys |
| Survive a node dying mid-backup | A half-written file that looks complete | Nothing counts until the manifest is written last |
| Know it is still working | Silence | Alerts for overdue backups, broken chains and lag |
From zero to restorable.
Install the chart
CRDs, the controller, the API and console, RBAC, alerts and the dashboard.
helm install keeper charts/keeper -n keeper-system --create-namespace \
  --set image.repository=registry.example.com/keeper/keeper --set image.tag=v0.1.0 \
  --set 'targetNamespaces={team-a}'
Point it at a bucket and your keys
Any S3-compatible store. Generate an age key with age-keygen and keep an offline copy.
apiVersion: keeper.republic.global/v1alpha1
kind: BackupStore
metadata: { name: main }
spec:
  s3:
    endpoint: https://s3.example.com
    region: us-east-1
    bucket: db-backups
    credentialsSecret: { namespace: keeper-system, name: keeper-s3 }
  encryption:
    ageRecipients: [age1…]   # public key only; the private key stays offline
Declare a target next to the database
Create the read-only users with the SQL in docs/sql/, then commit the target to git.
apiVersion: keeper.republic.global/v1alpha1
kind: BackupTarget
metadata: { name: app, namespace: team-a }
spec:
  engine: postgres
  endpoint: { host: postgres, port: 5432 }
  databases: [app]
  policy: prod             # nightly fulls, 7-day point-in-time window
  credentials:
    secretRef: { name: keeper-backup-postgres }
    replicationSecretRef: { name: keeper-repl-postgres }
Restore something, on purpose
The first full backup starts on its own. Then try the thing you hope you never need.
keeper targets
keeper restore team-a/app --at 2026-10-07T09:41:27Z --wait
keeper query <sandbox> -e "select count(*) from orders"
The full guide, every CRD field and the REST API are in the documentation.